Haoning Wu 「吴浩宁」PhD Candidate @ SJTUTop Talent Research Intern @ MiniMax I am currently a final-year PhD candidate at Shanghai Jiao Tong University (SJTU), fortunately advised by Prof. Weidi Xie and Prof. Ya Zhang. Before that, I received my B.Eng. degree in Information Engineering (IEEE Pilot Class) also from SJTU in 2022. I am generally interested in multi-modal learning, especially visual generative models and spatial intelligence. My long-term vision is to build Artificial General Intelligence (AGI) that surpasses human capabilities in perception, thinking, and action. Previously, I have gained internship experience at Shanghai AI Laboratory and Alibaba (Amap CV Lab). And now, I am a Top Talent research intern at MiniMax (Hailuo), working on building omni-modal foundation models for MiniMax-H3. Expected to graduate in Summer 2027, I am actively seeking opportunities as a research intern or full-time researcher for visual generative models, Omni-LLMs or embodied AI. I am always open to discussions and collaborations, feel free to reach out. Email: WeChat: |
|
News
- [2026.08] One paper (BasketEvent) has been accepted by BMVC 2026.
- [2026.07] Start internship at MiniMax as a Top Talent research intern, Beijing (on-site).
- [2026.06] One paper (OmniStream) has been accepted by ECCV 2026.
- [2026.04] One paper (SemanticREPA) has been accepted by CVPR 2026 HiGen Workshop.
- [2026.03] Start internship at Alibaba (Amap CV Lab) as a research intern, Beijing (on-site).
- [2026.02] Two papers (SpatialScore and SoccerMaster) have been accepted by CVPR 2026, and selected as Highlight and Oral (Award Candidate), respectively.
- [2025.11] One paper (SceneGen) has been accepted by 3DV 2026.
- [2025.08] Invited talk about our paper (MRGen) at NICE. Welcome to discuss!
- [2025.08] I will attend ICCV 2025 in person. See you in Hawaii!
- [2025.07] One paper (SoccerAgent) has been accepted by ACM Multimedia 2025.
- [2025.06] One paper (MRGen) has been accepted by ICCV 2025.
- [2025.02] One paper (UniSoccer) has been accepted by CVPR 2025.
- [2024.11] I am recognized as BMVC 2024 Outstanding Reviewer.
- [2024.10] One paper (MegaFusion) has been accepted by WACV 2025.
- [2024.09] One paper (MatchTime) has been accepted by EMNLP 2024 and selected as Oral.
- [2024.04] I will attend CVPR 2024 in person. See you in Seattle!
- [2024.04] I have passed my PhD Qualification Examination, and I am a PhD candidate now.
- [2024.04] Start internship at Shanghai AI Laboratory as a research intern, Shanghai (on-site).
- [2024.02] One paper (StoryGen) has been accepted by CVPR 2024.
- [2023.10] One paper (NeRF-SDP) has been accepted by ACM Multimedia Asia 2023 and selected as Oral.
- [2023.08] One paper (VFIAdapter) has been accepted by BMVC 2023 and selected as Oral.
Preprints / Tech Reports
| 2026 | |
|
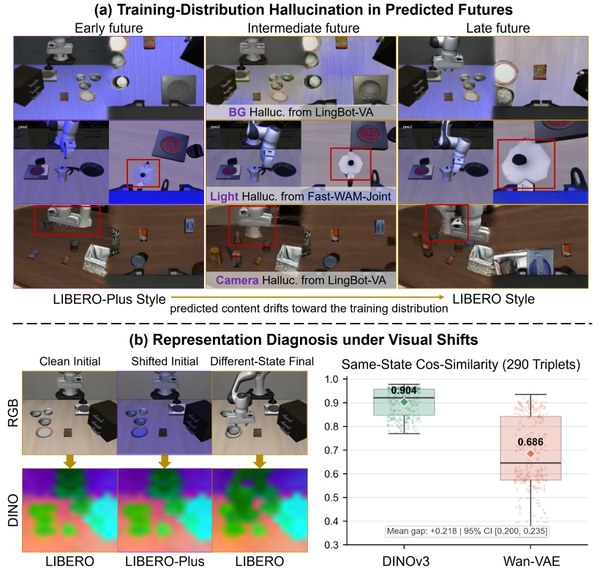
Mingxin Wang, Bin Hu, Bin Qian, Kaitao Jiang, Haoning Wu, et al. arXiv, 2026. (NEW) project page / arXiv / code / In this work, we propose ST-WAM, a world action model that uses DINOv3 features as a shared semantic space for future prediction and history retrieval, making robot manipulation more robust under visual distribution shifts. @article{wang2026stwam,
title={ST-WAM: Semantic-Temporal World Action Model for Robust Manipulation under Visual Distribution Shifts},
author={Wang, Mingxin and Hu, Bin and Qian, Bin and Jiang, Kaitao and Wu, Haoning and Yan, Feng and Jing, Bowen and Hao, Ruiyang and Wang, Enyi and Niu, Kangning and Yang, Yandan and Xu, Mu and Wang, Yan and Liu, Houde and Li, Tianlun},
journal={arXiv preprint arXiv:2607.28993},
year={2026}
}
|
|
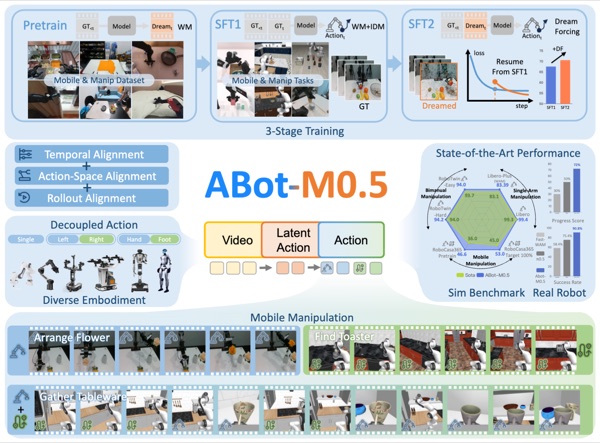
Ronghan Chen, Yandan Yang, Zuojin Tang, Dongjie Huo, Tong Lin, Haoning Wu, et al. arXiv, 2026. (NEW) project page / arXiv / code / Technical report of ABot-M0.5, a competitive foundation world action model (WAM). @article{chen2026abotm05,
title={ABot-M0.5: Unified Mobility-and-Manipulation World Action Model},
author={Chen, Ronghan and Yang, Yandan and Tang, Zuojin and Huo, Dongjie and Lin, Tong and Wu, Haoning and Liu, Haoyun and Chen, Yuzhi and Zheng, Lulu and Yuan, Botai and Li, Tianlun and Wang, Mingxin and Qi, Dekang and Hu, Bin and Mei, Wei and Xuan, Yuze and Yang, Haolong and Zhu, Yanqing and Xu, Mu and Ma, Zhiheng and Chang, Xinyuan},
journal={arXiv preprint arXiv:2607.00678},
year={2026}
}
|
|
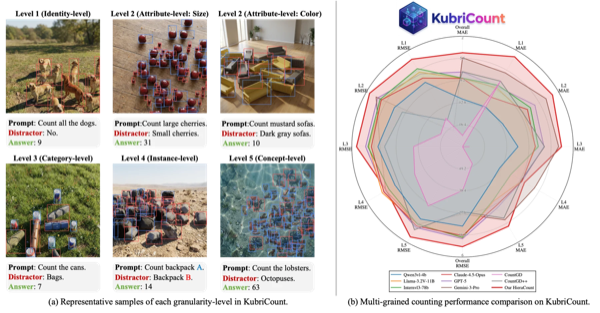
Chang Liu, Haoning Wu, Weidi Xie arXiv, 2026. (NEW) project page / arXiv / code / In this work, we re-define open-world counting as multi-grained counting, where visual exemplars specify target appearance and fine-grained text specifies the intended semantic granularity across five explicit levels. @article{liu2026count,
title={Count Anything at Any Granularity},
author={Liu, Chang and Wu, Haoning and Xie, Weidi},
journal={arXiv preprint arXiv:2605.10887},
year={2026}
}
|
|
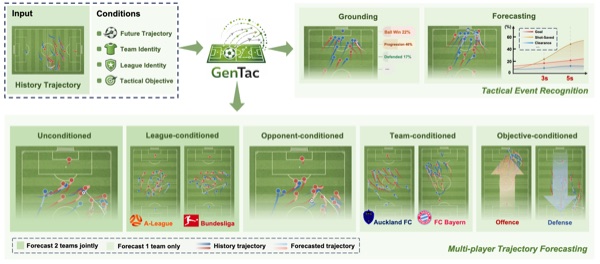
Jiayuan Rao, Tianlin Gui, Haoning Wu, Yanfeng Wang, Weidi Xie† arXiv, 2026. (NEW) project page / arXiv / code / In this work, we present GenTac, a diffusion-based framework that treats open-play soccer as a stochastic, multi-player process, generating plausible future trajectories, tactical events, and controllable counterfactuals. @article{rao2026gentac,
title={GenTac: Generative Modeling and Forecasting of Soccer Tactics},
author={Rao, Jiayuan and Gui, Tianlin and Wu, Haoning and Wang, Yanfeng and Xie, Weidi},
journal={arXiv preprint arXiv:2604.11786},
year={2026}
}
|
Publications
Showing selected papers. or see For the complete list, see Google Scholar for the complete list.
* denotes equal contribution, and † denotes corresponding author.
| 2026 | |
|
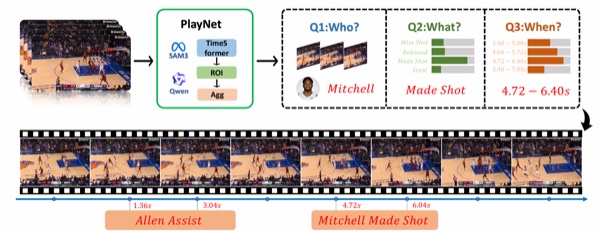
Yu Zhang, Jiayuan Rao, Haoning Wu, Weidi Xie† BMVC, 2026. (NEW) project page / arXiv / code / Given an input basketball video, our framework answers three player-centric questions: who performs the event, what event occurs, and when the key evidence appears. @article{zhang2026basketevent,
title={BasketEvent: Understanding Who Did What and When in Basketball Videos},
author={Zhang, Yu and Rao, Jiayuan and Wu, Haoning and Xie, Weidi},
journal={arXiv preprint arXiv:2607.21267},
year={2026}
}
|
|
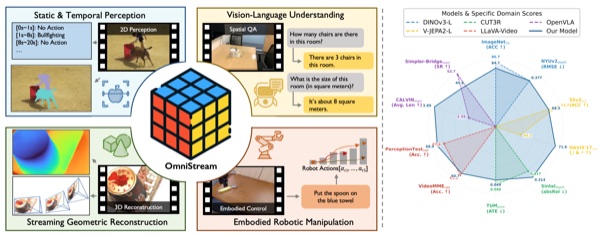
Yibin Yan*, Jilan Xu*, Shangzhe Di, Haoning Wu, Weidi Xie† ECCV, 2026. (NEW) project page / arXiv / code / In this work, we introduce OmniStream, a unified streaming visual backbone that effectively perceives, reconstructs, and acts from diverse visual inputs. @inproceedings{yan2026omnistream,
title={OmniStream: Mastering Perception, Reconstruction and Action in Continuous Streams},
author={Yan, Yibin and Xu, Jilan and Di, Shangzhe and Wu, Haoning and Xie, Weidi},
booktitle={European Conference on Computer Vision},
pages={53--74},
year={2026},
organization={Springer}
}
|
|
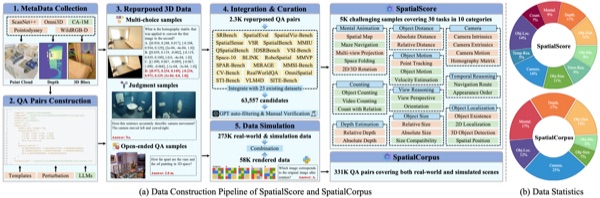
Haoning Wu*, Xiao Huang*, Yaohui Chen, Ya Zhang, Yanfeng Wang†, Weidi Xie† CVPR, 2026. (Highlight) (NEW) project page / arXiv / code / In this work, we investigate a critical question: to what extent do existing MLLMs possess spatial intelligence, encompassing both spatial perception and spatial understanding? @inproceedings{wu2025spatialscore,
author = {Wu, Haoning and Huang, Xiao and Chen, Yaohui and Zhang, Ya and Wang, Yanfeng and Xie, Weidi},
title = {SpatialScore: Towards Comprehensive Evaluation for Spatial Intelligence},
booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
year = {2026},
}
|
|
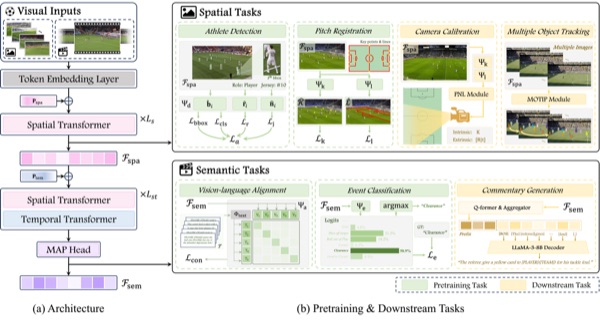
Haolin Yang, Jiayuan Rao, Haoning Wu, Weidi Xie† CVPR, 2026. (Oral Presentation | Award Candidate) (NEW) project page / arXiv / code / In this work, we present SoccerMaster, the first soccer-specific vision foundation model that unifies diverse understanding tasks within a single framework. @InProceedings{Yang_2026_CVPR,
author = {Yang, Haolin and Rao, Jiayuan and Wu, Haoning and Xie, Weidi},
title = {SoccerMaster: A Vision Foundation Model for Soccer Understanding},
booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
month = {June},
year = {2026},
pages = {21549-21560}
}
|
|
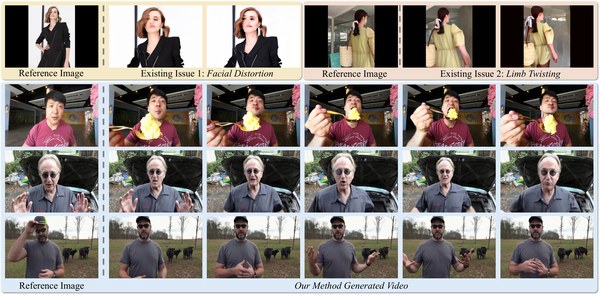
Chang Liu, Mengting Chen, Yixuan Huang, Haoning Wu, Chen Ju, Shuai Xiao, Jinsong Lan, Yanfeng Wang CVPR HiGen Workshop, 2026. (NEW) paper / arXiv / In this work, we propose SemanticREPA, which uses human-specific semantic representations (video depth and face identity features) as supervision through representation alignment rather than as extra conditions, yielding more coherent body structures and better identity preservation in human image animation. @InProceedings{Liu_2026_CVPR,
author = {Liu, Chang and Chen, Mengting and Huang, Yixuan and Wu, Haoning and Ju, Chen and Xiao, Shuai and Lan, Jinsong and Wang, Yanfeng},
title = {Improving Human Image Animation via Semantic Representation Alignment},
booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR) Workshops},
month = {June},
year = {2026},
pages = {5704-5714}
}
|
|
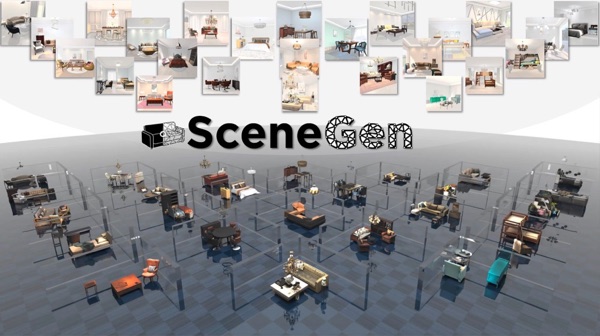
Yanxu Meng*, Haoning Wu*, Ya Zhang, Weidi Xie† 3DV, 2026. (NEW) project page / arXiv / code / In this work, we propose a feedforward 3D scene generation model that can simultaneously synthesize multiple 3D assets from a single image. @inproceedings{meng2026scenegen,
author = {Meng, Yanxu and Wu, Haoning and Zhang, Ya and Xie, Weidi},
title = {SceneGen: Single-Image 3D Scene Generation in One Feedforward Pass},
booktitle = {International Conference on 3D Vision 2026},
year = {2026},
}
|
| 2025 | |
|
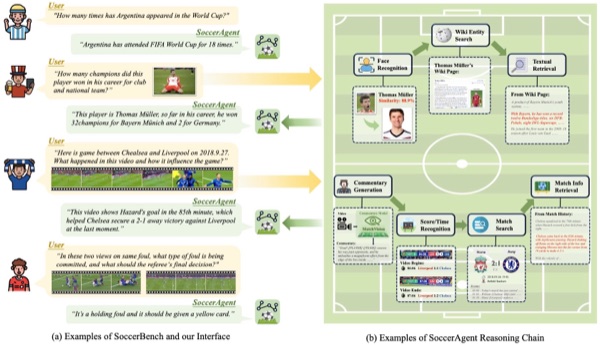
Jiayuan Rao*, Zifeng Li*, Haoning Wu, Ya Zhang, Yanfeng Wang†, Weidi Xie† ACM Multimedia, 2025. project page / arXiv / code / In this work, we present SoccerBench, the largest and most comprehensive soccer-specific benchmark, along with a multi-agent system, SoccerAgent, for soccer understanding. @inproceedings{rao2025soccceragent,
title = {Multi-Agent System for Comprehensive Soccer Understanding},
author = {Rao, Jiayuan and Li, Zifeng and Wu, Haoning and Zhang, Ya and Wang, Yanfeng and Xie, Weidi},
booktitle = {ACM Multimedia 2025},
year = {2025}
}
|
|
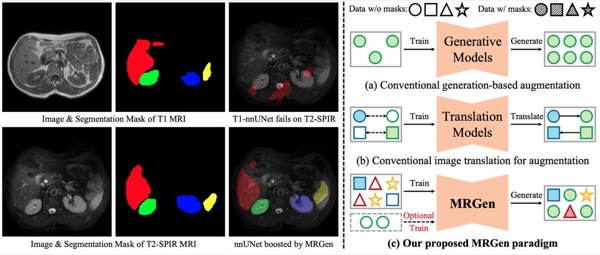
Haoning Wu*, Ziheng Zhao*, Ya Zhang, Yanfeng Wang†, Weidi Xie† ICCV, 2025. project page / arXiv / code / In this work, we establish a novel paradigm for generative models in medical applications: controllably synthesizing data for underrepresented modalities. @inproceedings{wu2025mrgen,
author = {Wu, Haoning and Zhao, Ziheng and Zhang, Ya and Wang, Yanfeng and Xie, Weidi},
title = {MRGen: Segmentation Data Engine for Underrepresented MRI Modalities},
booktitle = {Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV)},
year = {2025},
}
|
|
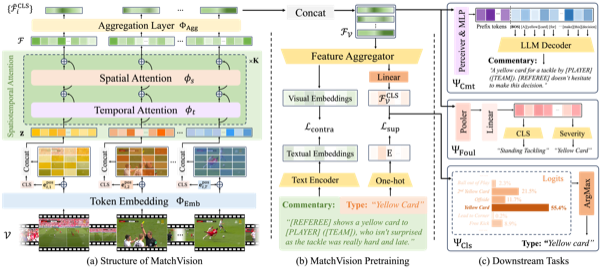
Jiayuan Rao*, Haoning Wu*, Hao Jiang, Ya Zhang, Yanfeng Wang†, Weidi Xie† CVPR, 2025. project page / arXiv / code / In this work, we present the first visual-language foundation model tailored for soccer video understanding, which can be applied to various downstream tasks. @inproceedings{rao2024unisoccer,
title = {Towards Universal Soccer Video Understanding},
author = {Rao, Jiayuan and Wu, Haoning and Jiang, Hao and Zhang, Ya and Wang, Yanfeng and Xie, Weidi},
booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
year = {2025},
}
|
|
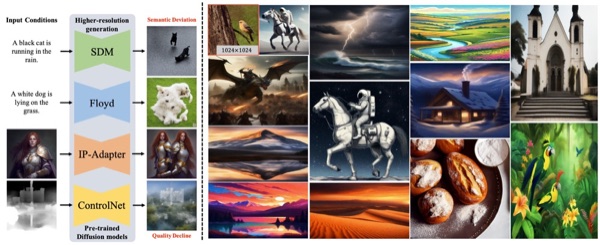
Haoning Wu*, Shaocheng Shen*, Qiang Hu, Xiaoyun Zhang†, Ya Zhang, Yanfeng Wang WACV, 2025. project page / arXiv / code / In this work, we propose a tuning-free strategy to extend the higher-resolution image generation capabilities of existing diffusion models. @InProceedings{wu2024megafusion,
author = {Wu, Haoning and Shen, Shaocheng and Hu, Qiang and Zhang, Xiaoyun and Zhang, Ya and Wang, Yanfeng},
title = {MegaFusion: Extend Diffusion Models towards Higher-resolution Image Generation without Further Tuning},
booktitle = {Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision (WACV)},
year = {2025},
}
|
| 2024 | |
|
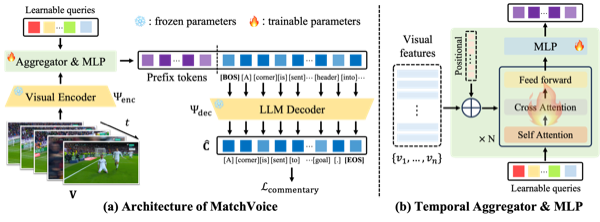
Jiayuan Rao*, Haoning Wu*, Chang Liu, Yanfeng Wang†, Weidi Xie† EMNLP, 2024. (Oral Presentation) project page / arXiv / code / In this work, we focus on building a visual-language model for automatic soccer game commentary generation. @inproceedings{rao2024matchtimeautomaticsoccergame,
title = {MatchTime: Towards Automatic Soccer Game Commentary Generation},
author = {Rao, Jiayuan and Wu, Haoning and Liu, Chang and Wang, Yanfeng and Xie, Weidi},
booktitle = {Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing},
year = {2024}
}
|
|
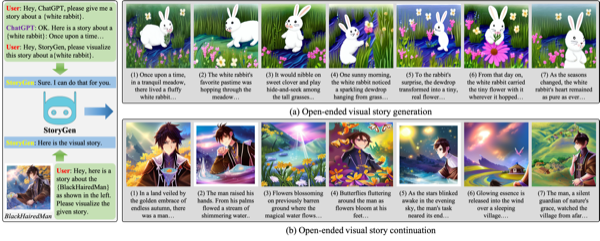
Chang Liu*, Haoning Wu*, Yujie Zhong, Xiaoyun Zhang, Yanfeng Wang†, Weidi Xie† CVPR, 2024. project page / arXiv / code / In this work, we focus on the task of generating a coherent image sequence based on a given storyline, denoted as open-ended visual storytelling. @InProceedings{Liu_2024_CVPR,
author = {Liu, Chang and Wu, Haoning and Zhong, Yujie and Zhang, Xiaoyun and Wang, Yanfeng and Xie, Weidi},
title = {Intelligent Grimm - Open-ended Visual Storytelling via Latent Diffusion Models},
booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
month = {June},
year = {2024},
pages = {6190-6200}
}
|
| 2023 | |
|
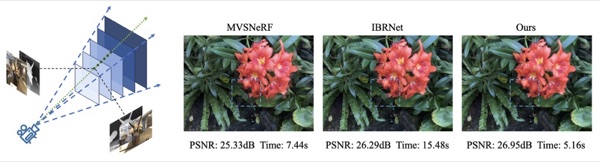
Qiuwen Wang, Shuai Guo, Haoning Wu, Rong Xie, Li Song†, Wenjun Zhang ACM Multimedia Asia, 2023. (Oral Presentation) paper / code / In this work, we propose a novel framework, termed as NeRF-SDP, to address the challenge of balancing rendering speed and quality in generalizable NeRF. @inproceedings{Wang_2023,
title = {NeRF-SDP: Efficient Generalizable Neural Radiance Field with Scene Depth Perception},
author = {Wang, Qiuwen and Guo, Shuai and Wu, Haoning and Xie, Rong and Song, Li and Zhang, Wenjun},
booktitle = {ACM Multimedia Asia 2023},
series = {MMAsia '23},
publisher = {ACM},
pages = {1--7},
year = {2023},
month = dec,
doi = {10.1145/3595916.3626380}
}
|
|
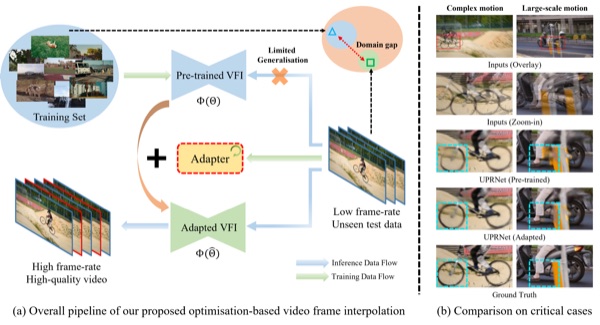
Haoning Wu, Xiaoyun Zhang†, Weidi Xie, Ya Zhang, Yanfeng Wang† BMVC, 2023. (Oral Presentation) project page / arXiv / code / In this work, we propose a novel optimization-based VFI method that can adapt to unseen motions at test time and boost existing pre-trained models. @inproceedings{Wu_2023_BMVC,
author = {Haoning Wu and Xiaoyun Zhang and Weidi Xie and Ya Zhang and Yan-Feng Wang},
title = {Boost Video Frame Interpolation via Motion Adaptation},
booktitle = {34th British Machine Vision Conference 2023, {BMVC} 2023, Aberdeen, UK, November 20-24, 2023},
publisher = {BMVA},
year = {2023},
url = {https://papers.bmvc2023.org/0179.pdf}
}
|
| 2022 | |
|
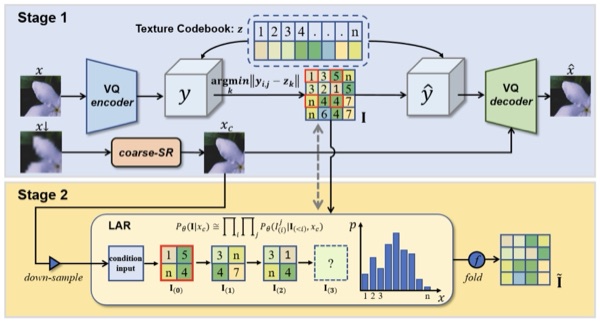
Baisong Guo*, Xiaoyun Zhang*†, Haoning Wu, Yu Wang, Ya Zhang, Yanfeng Wang† CVPR, 2022. paper / code / In this work, we propose LAR-SR for super-resolution based on a Local AutoRegressive module, achieving superior performance among generative models for SR. @InProceedings{Guo_2022_CVPR,
author = {Guo, Baisong and Zhang, Xiaoyun and Wu, Haoning and Wang, Yu and Zhang, Ya and Wang, Yan-Feng},
title = {LAR-SR: A Local Autoregressive Model for Image Super-Resolution},
booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
month = {June},
year = {2022},
pages = {1909-1918}
}
|
Education
- PhD Student, Shanghai Jiao Tong University (SJTU), Sep. 2022 - Present (Jun. 2027, expected)
- B.Eng. in Information Engineering (IEEE Pilot Class), Shanghai Jiao Tong University (SJTU), Sep. 2018 - Jun. 2022
Internship
- Top Talent Research Intern, MiniMax (Hailuo), Beijing, China, Jul. 2026 - Present
- Research Intern, Alibaba (Amap CV Lab), Beijing, China, Mar. 2026 - Jun. 2026
- Research Intern, Shanghai AI Laboratory, Shanghai, China, Apr. 2024 - Mar. 2026
Awards
- [2026] CVPR 2026 Award Candidate
- [2024] BMVC 2024 Outstanding Reviewer
- [2021] China National Scholarship (for Undergraduates)
- [2021] School Scholarship B Prize
- [2020] School Scholarship C Prize
Reviewer Service
- Computer Vision and Pattern Recognition (CVPR 2023, 2024, 2025, 2026)
- International Conference on Computer Vision (ICCV 2023, 2025)
- European Conference on Computer Vision (ECCV 2024, 2026)
- ACM Multimedia (ACM MM 2024, 2025, 2026)
- British Machine Vision Conference (BMVC 2024, 2025) (Outstanding Reviewer in 2024)
- AAAI Conference on Artificial Intelligence (AAAI 2025, 2026, 2027)
- Conference on Neural Information Processing Systems (NeurIPS 2025)
- Winter Conference on Applications of Computer Vision (WACV 2026)
- International Conference on 3D Vision (3DV 2026)
- IEEE Transactions on Visualization and Computer Graphics (TVCG)
- IEEE Transactions on Multimedia (TMM)
Misc
Occasional notes on research and life, kept as they were written at the time.
- [2026.10] Hello, world: why I keep these notes